Definition
A canonical tag is a line of HTML that tells search engines which URL is the preferred version of a page when several URLs show similar content. Google treats it as a strong hint rather than a directive, and may select a different canonical URL than the one declared.
Why it matters
Most sites serve the same content at more than one address without meaning to. Tracking parameters, filters, print versions, trailing slashes and both http and https versions all produce separate URLs. Left alone, search engines have to guess which one to index, and the guess may not be yours.
It is also behind one of the most common messages in Search Console, which is the reason many people look the term up at all.
How it works
The tag sits in the head of the page:
<link rel="canonical" href="https://www.example.com/blue-widget" />
It says: of all the URLs showing this content, this is the one to index. Google's SEO starter guide treats it as standard practice on any site that can serve one page at several addresses. Google's documentation on consolidating duplicate URLs describes it as one of several signals it uses to pick a canonical, alongside redirects, sitemap inclusion and internal linking patterns.
That word "signals" is the part people miss. The tag is a strong hint, not an instruction. If the declared canonical contradicts the other evidence, for example if every internal link points somewhere else, Google may select a different URL. Declaring it and then undermining it elsewhere is how sites end up arguing with their own markup.
"Alternate page with proper canonical tag"
This Search Console message is not an error, and it is the reason this term gets searched. It means Google found the page, saw that it declares a different URL as canonical, respected that, and indexed the other one instead. That is the system working exactly as intended.
It is worth investigating only when the page it names is one you actually wanted indexed. In that case the canonical is pointing at the wrong URL, which is a content management problem rather than a crawling one.
Worked example
A product reachable through several filters should name one address:
- https://shop.example.com/widgets/bluethe canonical target
- https://shop.example.com/widgets/blue?ref=emailnames the target above
- https://shop.example.com/widgets?colour=bluenames the target above
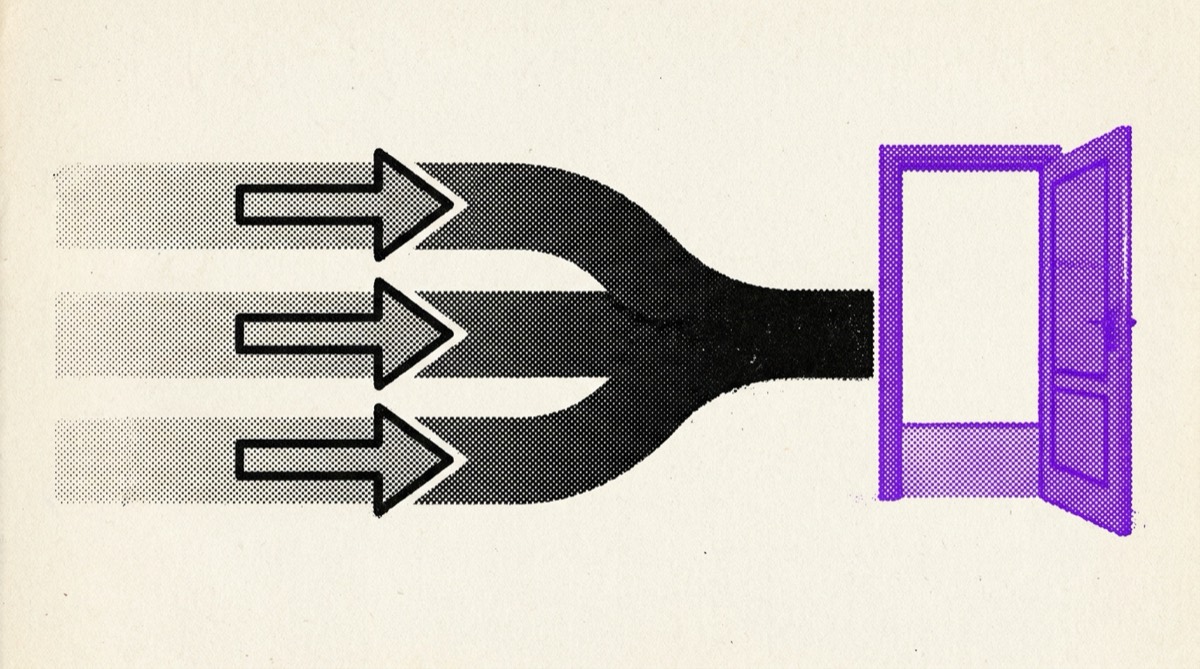
Every one of those pages carries the same canonical tag pointing at the first. This is the standard answer to the duplication that faceted navigation produces, and it is the difference between one indexed product page and dozens of near-identical ones diluting each other.
Common mistakes
- Pointing every page at the home page.A canonical should name a page with the same content, not the site root. Google ignores canonicals that are clearly wrong.
- Canonical plus noindex on the same page.Contradictory instructions. One says index this other URL, the other says index nothing.
- Relative URLs.Use absolute ones. A relative canonical that resolves wrongly points at a URL that does not exist.
- Canonicalising paginated pages to page one.Page two is not a duplicate of page one, and collapsing them hides its content.
- Expecting it to work like a redirect.Users still land on the URL they clicked. If you want them moved, that is a 301 redirect.
When to use which
If the duplicate URL should not exist at all, redirect it. If it needs to keep working for users, for example a filtered view people share, keep it and canonicalise it. That distinction, applied consistently, resolves most of the duplicate content findings in a technical SEO audit.