Definition
Duplicate content is substantially similar content appearing on more than one URL, either within a site or across sites. Google groups such URLs and selects one to show. It is not treated as spam unless the duplication is deliberate and manipulative.
Why it matters
Duplicate content is the subject of more bad advice than almost anything else in SEO, most of it built on a penalty that does not exist. Knowing what the real cost is changes what you spend time fixing.
The real costs are two. Google has to choose which version to show, and it may not choose the one you want. And crawling many near-identical URLs spends crawl budget that could have gone to pages you care about.
How it works
Google's documentation on duplicate content describes grouping similar URLs and selecting one as canonical, then showing that one in results. The others are not removed from the web, they are simply not the version displayed.
On the question of penalties, Google's spam policies are specific. What is penalised is scraped content and deliberately duplicated content created to manipulate rankings. An ecommerce site serving the same product through three filter combinations is not doing that, and is not penalised for it.
Most duplication on real sites is accidental and structural, and resolving it is routine technical SEO work:
- The same page at
httpandhttps, or with and withoutwww - Tracking parameters producing new URLs for the same page
- Faceted navigation generating a URL per filter combination
- Printer-friendly versions
- Product descriptions supplied by a manufacturer and used by every retailer
Worked example
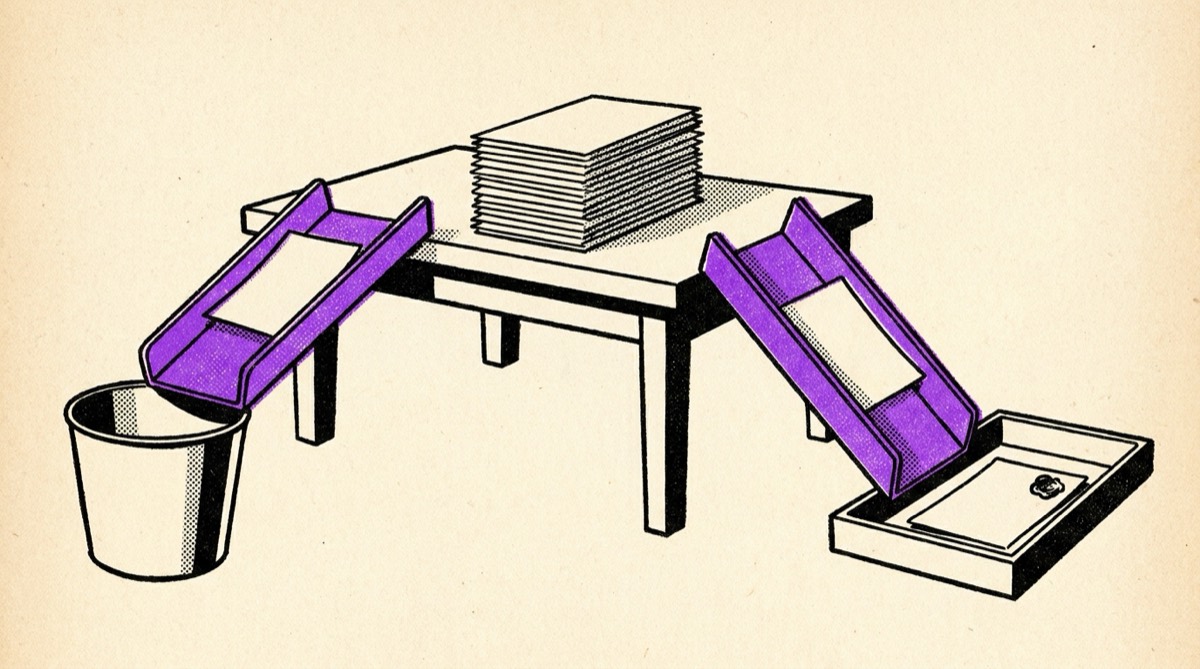
The resolution depends on whether the duplicate URL should exist at all:
- Should not exist301 redirect to the real URL
- Must stay for userscanonical tag naming the real URL
- Generated by filterscanonical, and consider robots.txt for combinations with no search demand
- Syndicated to another siteask for a canonical or a link back
Manufacturer descriptions are the case worth calling out separately. Every retailer selling the same item has identical text, so none of them is distinguished by it. The fix is not a technical one. It is writing something the manufacturer did not supply.
Common mistakes
- Believing in a duplicate content penalty.There is no such penalty for ordinary duplication. Chasing it wastes effort better spent elsewhere.
- Blocking duplicates in robots.txt when a canonical is needed.A blocked URL cannot be read, so the canonical tag on it is never seen, and the duplicate can still be indexed from links.
- Rewriting pages that are not actually duplicates.Two pages on related topics are not duplicates. If they compete for the same search, that is keyword cannibalisation, which is a different problem with a different fix.
- Ignoring parameters.Tracking parameters quietly multiply URLs. A canonical on the clean URL resolves it.
- Serving both www and non-www.Pick one, redirect the other, and be consistent in internal links and the sitemap.
How to find it
Search Console's page indexing report names the pages it excluded and why, including those excluded as duplicates with a different canonical selected. That report is the shortest route to the real picture, because it is Google's own account of which of your URLs it decided to keep.