Definition
An XML sitemap is a file listing the URLs on a site that their owner wants search engines to know about, with optional information such as when each was last modified. It helps with discovery of pages, and it does not mean any of them will be indexed.
Why it matters
A sitemap is how a large or poorly linked site tells search engines what exists. For a small, well linked site it adds little, because internal linking already does the job. For a site with thousands of pages, or new pages appearing daily, it is the difference between being found this week and being found eventually.
The limit is worth stating first, because it is where expectations usually break: a sitemap assists discovery. It does not cause indexing.
How it works
The format is defined by the sitemaps protocol, which Google, Bing and others support. Each entry is a URL with optional metadata:
<url>
  <loc>https://www.example.com/glossary/xml-sitemap</loc>
  <lastmod>2026-10-28</lastmod>
</url>
Google's documentation on sitemaps sets the limits: 50,000 URLs and 50MB uncompressed per file. Beyond that you split into several files and reference them from a sitemap index, which is a file of files rather than of URLs.
Google uses lastmod when it is trustworthy. A sitemap where every URL claims to have changed at the moment the file was generated teaches the crawler to ignore the field, which is a self-inflicted loss. The date should reflect when the content actually changed.
Sitemaps are declared either in robots.txt or by submitting them in Search Console, and keeping them accurate is part of any technical SEO engagement.
Worked example
The rule for what belongs is narrow: URLs you want indexed, in their canonical form, returning 200.
- IncludePublished pages you want in search results
- ExcludeRedirected URLs, 404s, noindexed pages
- ExcludeNon-canonical duplicates and parameter variants
- ExcludePages blocked in robots.txt
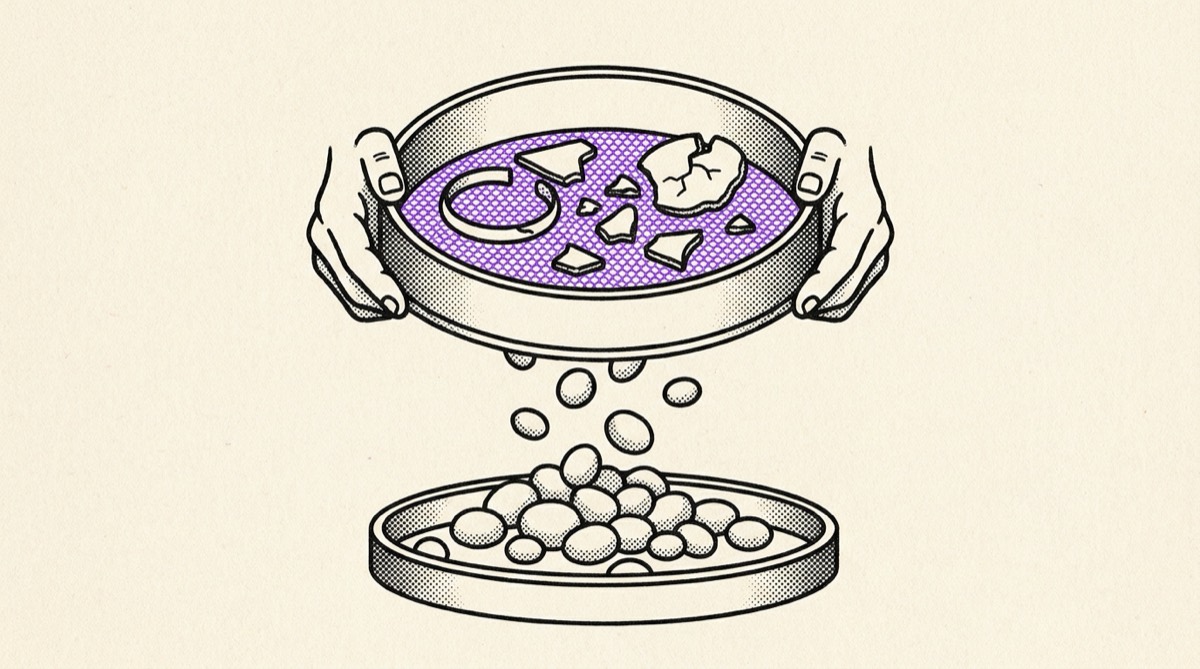
Splitting by section is worth doing on any site with distinct content types. Search Console reports coverage per submitted sitemap, so separating, for example, a blog from a glossary from the rest of the site turns one undifferentiated number into three readable ones.
Common mistakes
- Including URLs that redirect.A sitemap entry pointing at a 301 sends a crawler to a URL you have already said is gone.
- Including non-canonical URLs.It contradicts your own canonical tags.
- Faking lastmod.Setting it to the build time on every entry makes the field worthless.
- Expecting it to force indexing.Google decides what to index. A sitemap gets a page considered, nothing more.
- Letting it go stale.A sitemap listing pages deleted a year ago is a maintenance signal, and not a good one.
What it cannot fix
If pages are not being indexed, a sitemap is rarely the answer. The usual causes are thin content, duplication, or pages that nothing links to. Submitting a list of them more insistently does not change the assessment. The page indexing report in Search Console will say which reason applies, and it is a better starting point than regenerating the file.